 15 Topics
 10 Days
 75 Sessions
Programme Overview
Training Description
Who Should Attend
Session Objectives
- Understand the fundamentals of real-time data pipelines.
- Understand the fundamentals of real-time data pipelines.
- Utilize message queues and distributed systems for data ingestion.
- Implement data transformation and aggregation in real-time.
- Design and build scalable real-time data processing systems.
- Optimize data pipelines for low latency and high throughput.
- Troubleshoot and address common issues in real-time systems.
- Implement data serialization and schema management for streaming data.
- Integrate real-time data pipelines with various data storage and analytics platforms.
- Understand how to handle data consistency and fault tolerance in real-time systems.
- Explore advanced real-time data processing techniques (e.g., windowing, state management).
- Apply real world use cases for real-time data pipelines.
- Leverage real-time data processing tools and frameworks for efficient implementation.
About the Course
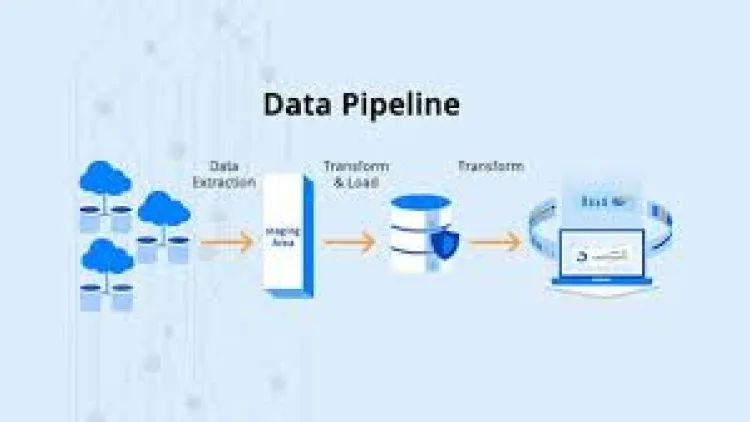
This advanced training equips participants with the knowledge and practical skills to design, build, deploy, monitor, and optimize real-time data pipelines for continuously generated and high-volume data. The course focuses on modern streaming architectures that enable organizations to capture, process, transform, analyze, and deliver data with minimal latency.Participants will explore event-driven architectures, stream ingestion, real-time processing, data transformation, message brokers, streaming analytics, fault tolerance, scalability, monitoring, security, and cloud-based data pipeline deployment. The training emphasizes practical approaches for building reliable, high-performance pipelines that support real-time business intelligence and operational decision-making.
Curriculum & Topics
15 Topics | 75 Sessions
-
 Workshop 1.1:
Fundamentals of real-time data pipelines.
-
Workshop 1.2:
Overview of stream processing, message queues, and distributed systems.
-
Workshop 1.3:
Setting up a real-time data processing development environment.
-
Workshop 1.4:
Introduction to real-time data processing tools and frameworks.
-
Workshop 1.5:
Best practices for real-time data pipelines.
-
Workshop 2.1:
Mastering stream processing concepts and technologies.
-
Workshop 2.2:
Understanding data streams, event processing, and windowing.
-
Workshop 2.3:
Designing and building stream processing applications.
-
Workshop 2.4:
Optimizing stream processing for low latency.
-
Workshop 2.5:
Best practices for stream processing.
-
Workshop 3.1:
Utilizing message queues and distributed systems for data ingestion.
-
Workshop 3.2:
Implementing message brokers (e.g., Kafka, RabbitMQ).
-
Workshop 3.3:
Designing and building distributed data pipelines.
-
Workshop 3.4:
Optimizing data ingestion for high throughput.
-
Workshop 3.5:
Best practices for message queues.
-
Workshop 4.1:
Implementing data transformation and aggregation in real-time.
-
Workshop 4.2:
Utilizing stream processing libraries and frameworks.
-
Workshop 4.3:
Designing and building data transformation workflows.
-
Workshop 4.4:
Optimizing data aggregation for real-time analytics.
-
Workshop 4.5:
Best practices for data transformation.
-
Workshop 5.1:
Designing and building scalable real-time data processing systems.
-
Workshop 5.2:
Utilizing distributed computing frameworks (e.g., Apache Flink, Apache Spark Streaming).
-
Workshop 5.3:
Implementing data partitioning and parallel processing.
-
Workshop 5.4:
Optimizing systems for scalability and performance.
-
Workshop 5.5:
Best practices for scalable systems.
-
Workshop 6.1:
Optimizing data pipelines for low latency and high throughput.
-
Workshop 6.2:
Utilizing performance tuning and monitoring tools.
-
Workshop 6.3:
Implementing data buffering and caching strategies.
-
Workshop 6.4:
Designing efficient data processing architectures.
-
Workshop 6.5:
Best practices for pipeline optimization.
-
Workshop 7.1:
Debugging common issues in real-time systems.
-
Workshop 7.2:
Analyzing system logs and error messages.
-
Workshop 7.3:
Utilizing troubleshooting techniques for problem resolution.
-
Workshop 7.4:
Resolving common data processing errors.
-
Workshop 7.5:
Best practices for troubleshooting.
-
Workshop 8.1:
Implementing data serialization and schema management for streaming data.
-
Workshop 8.2:
Utilizing Avro, Protobuf, and JSON schema.
-
Workshop 8.3:
Designing and building schema registries.
-
Workshop 8.4:
Optimizing data serialization for performance.
-
Workshop 8.5:
Best practices for data serialization.
-
Workshop 9.1:
Integrating real-time data pipelines with various data storage and analytics platforms.
-
Workshop 9.2:
Utilizing data streaming connectors and APIs.
-
Workshop 9.3:
Implementing data integration with external databases and data lakes.
-
Workshop 9.4:
Optimizing integration for data retrieval and analysis.
-
Workshop 9.5:
Best practices for integration.
-
Workshop 10.1:
Understanding how to handle data consistency and fault tolerance in real-time systems.
-
Workshop 10.2:
Utilizing data replication and checkpointing.
-
Workshop 10.3:
Implementing fault-tolerant data pipelines.
-
Workshop 10.4:
Designing robust data processing workflows.
-
Workshop 10.5:
Best practices for consistency.
-
Workshop 11.1:
Exploring advanced real-time data processing techniques (windowing, state management).
-
Workshop 11.2:
Utilizing windowing for time-based data aggregation.
-
Workshop 11.3:
Implementing state management for complex event processing.
-
Workshop 11.4:
Designing and building advanced real-time solutions.
-
Workshop 11.5:
Optimizing advanced techniques for specific applications.
-
Workshop 11.6:
Best practices for advanced techniques.
-
Workshop 12.1:
Implementing real-time data pipelines for IoT data processing.
-
Workshop 12.2:
Utilizing real-time data for fraud detection and security monitoring.
-
Workshop 12.3:
Implementing real-time data for log aggregation and analytics.
-
Workshop 12.4:
Utilizing real-time data for financial transaction processing.
-
Workshop 12.5:
Best practices for real-world applications.
-
Workshop 13.1:
Utilizing real-time data processing tools and frameworks (Apache Flink, Kafka Streams).
-
Workshop 13.2:
Implementing data pipelines with specific tools.
-
Workshop 13.3:
Designing and building automated deployment workflows.
-
Workshop 13.4:
Optimizing tool usage for efficient development.
-
Workshop 13.5:
Best practices for tool implementation.
-
Workshop 14.1:
Implementing pipeline monitoring and logging for real-time systems.
-
Workshop 14.2:
Utilizing monitoring tools and metrics.
-
Workshop 14.3:
Designing and building performance dashboards.
-
Workshop 14.4:
Optimizing monitoring for real-time insights.
-
Workshop 14.5:
Best practices for monitoring.
-
Workshop 15.1:
Emerging trends in real-time data processing.
-
Workshop 15.2:
Utilizing AI for real-time data analysis.
-
Workshop 15.3:
Implementing real-time data mesh architectures.
-
Workshop 15.4:
Best practices for future applications.